 Balinder Walia
Google’s Gemini 4 Argon is a frontier model built to work for a long time on one hard problem: migrating a codebase, patching vulnerabilities, or researching a finance or legal question end to end. Here is the Workstation take: what shipped, what it costs, where it fits next to the models you already run, and the workflows we would put it on first. Code, diagrams and ten worked workflows are in the long article.
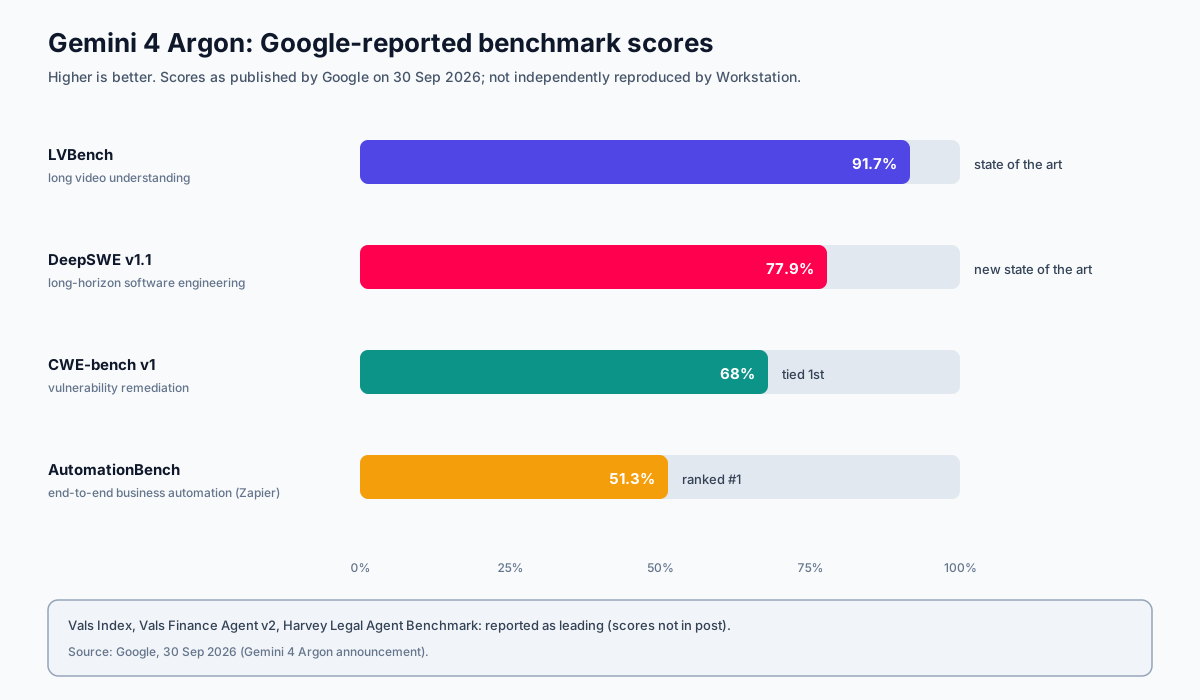
gemini-4-argon) shares one 1M-token window across input, thinking and output, where earlier Gemini models stopped output at 64K tokens. It leads Google’s reported results on long-horizon software engineering (DeepSWE v1.1, 77.9%), business automation (AutomationBench, 51.3%) and long-video understanding (LVBench, 91.7%), and ties for first on vulnerability remediation (CWE-bench v1, 68%). It is on the paid Gemini API tier now, at $2 / $10 per million input / output tokens until 30 November, then $4 / $20. Use it where one long, verifiable run replaces days of human work. Keep a fast model for the volume.
Rewritten for Workstation readers from Google’s announcement, Gemini 4 Argon: our next era of frontier intelligence (30 Sep 2026), and the AI Studio developer guide (13 Oct 2026). Benchmark figures are Google’s own; check current prices before you budget.
What actually shipped
- 30 September: announced, and released first to vetted cyber defenders through Google’s Fairwind Program while safeguards were tested.
- 13 October: available to developers on the paid tier of the Gemini API (Google AI Studio, Android Studio), to Google AI Ultra subscribers, and in Google Antigravity, Google’s agent-first development platform.
- One window for everything: input, thinking and output share 1M tokens. Output defaults to 64K. Above that you run the request in the background (“long decode”) and the model can return whole multi-file diffs, test suites or proofs in one pass.
- Three thinking levels:
lowfor routing and extraction,medium(default) for everyday coding and tool use,highfor root-cause debugging, security patching and architecture.
The numbers Google reported
Benchmarks only tell you so much. The internal results are more useful, because they describe work a business would pay for:
- Memory: a team of Argon agents read fleet-wide profiling data and applied optimisations that freed over 300 TiB of memory across Google’s data centres, with 500 TiB to 1 PiB expected in total.
- Migrations: Argon agents are porting C and C++ to Rust across Google, from libraries with tens of thousands of lines up to the 800K+ line Fuchsia Zircon kernel. Every port goes through automated and manual audit, emulation testing and review before production.
- Performance: on libgav1, Google’s open-source video decoder, Argon replaced 32K lines of hand-written SIMD with safe Rust that the compiler vectorises itself. The result is 2.7x faster than the earlier Rust port, with identical output.
- Research: on a quantum computing subroutine, it beat the published resource baseline by 40% in minutes.
Why business owners should care
- Backlog work that never gets staffed. Legacy migrations, dependency upgrades, performance clean-ups and security debt are long, measurable and dull: exactly the shape Argon was trained for.
- Knowledge work across formats. It reads PDFs, spreadsheets, ledgers, filings and long videos together and turns them into a report, a redline or a dashboard. Google reports it leading Vals Finance Agent v2 and Harvey’s legal agent benchmark.
- Cheaper repeat runs. Cached input is 95% off, and caching is automatic. Agents that re-read the same codebase or policy pack each turn get much cheaper.
- Defence, not just speed. It finds, validates and patches vulnerabilities. Wiz used it to find a critical exposure in hospital software that earlier models had missed.
Why developers should care
- Give it a target and a test, then step back. Argon does its best work when it can check itself against a real signal: your test suite, a benchmark script, browser screenshots, runtime logs.
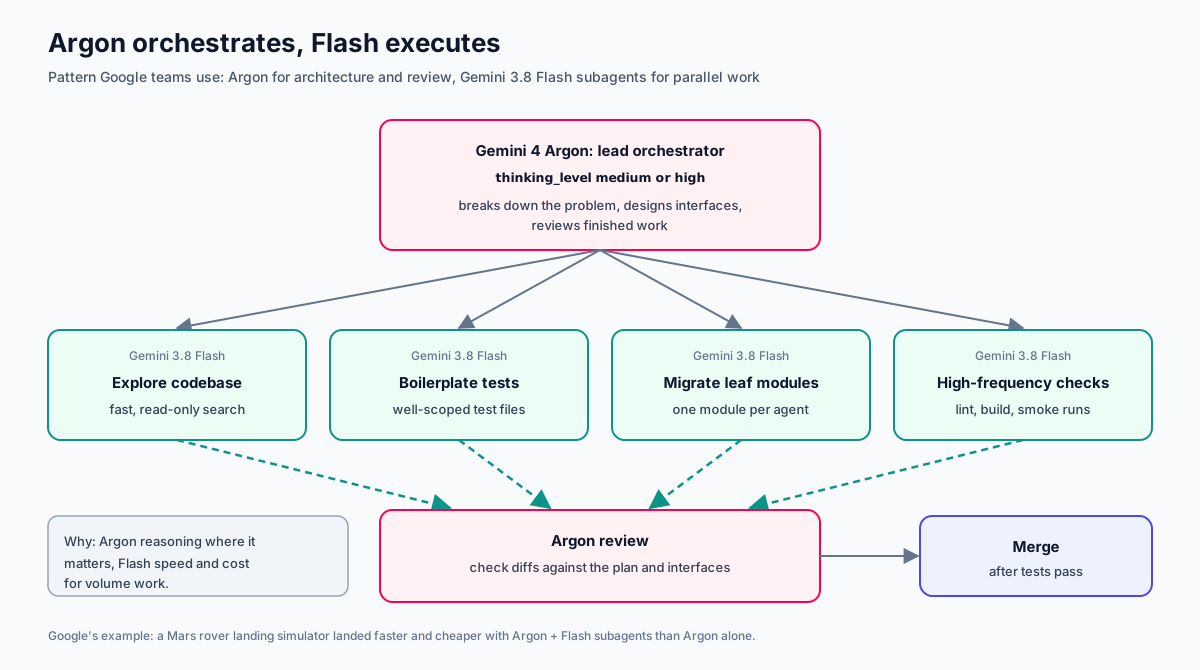
- Use it as the lead, not the whole team. Google’s own engineers pair Argon (planning, interfaces, review) with fast Gemini 3.8 Flash subagents for the parallel, well-scoped work. It is faster and cheaper than Argon alone.
- Migration clean-up. Replace
thinking_budgetwiththinking_level, droptemperature/top_p/top_k(ignored), remove explicit context caches, and raise client timeouts to 15–20 minutes or run in the background.
Five workflows we would start with
| Workflow | Why Argon | The check that keeps it honest |
|---|---|---|
| Legacy module migration | Holds a whole subsystem in context and iterates for hours | Differential tests: old and new code give identical output |
| Vulnerability backlog | Finds, proves and patches in one loop | Proof of concept in a sandbox, then human security review |
| Cloud cost and memory tuning | Reads months of metrics and turns them into concrete changes | Staged rollout with automatic rollback on SLO breach |
| Month-end finance pack | Cross-references ledgers, PDFs and spreadsheets | Every figure cites its source cell; totals reconcile |
| Incident post-mortem | Watches the call recording and reads the dashboards together | Timeline matches logs to the minute; owner signs off |
All ten workflows, with prompts, code and pipeline YAML, are in the long article.
What it costs, in plain numbers
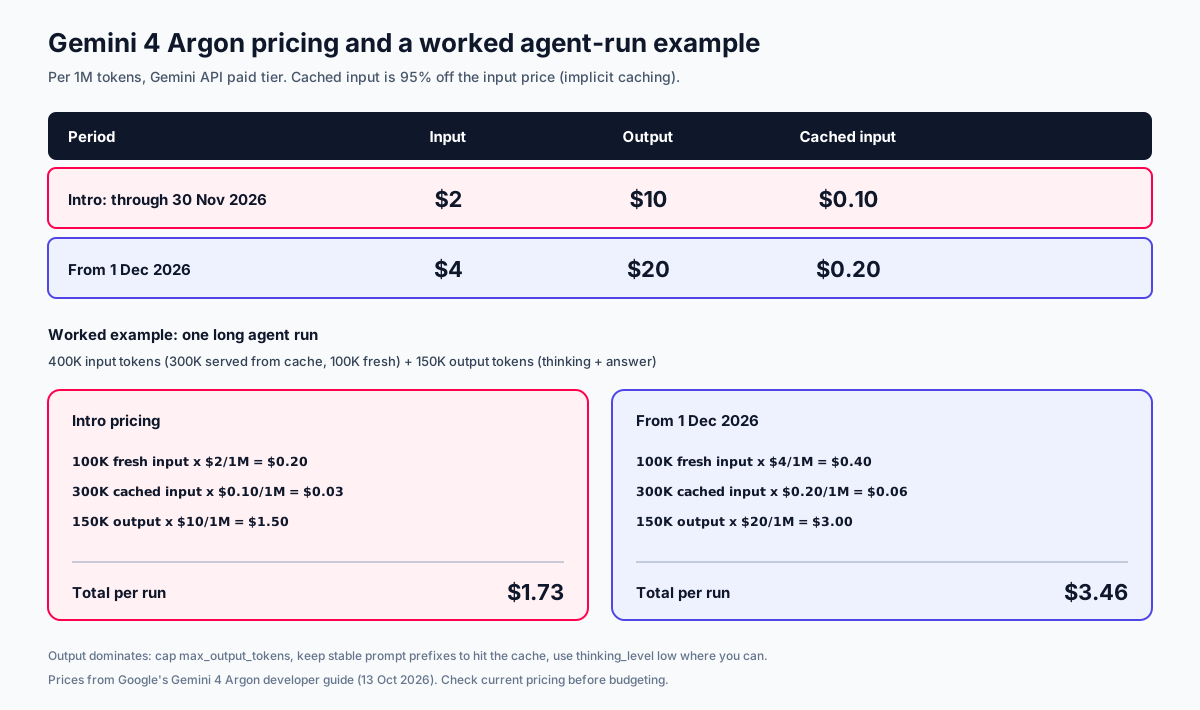
A typical long agent run that reads 400K tokens (300K of them cached from earlier turns) and writes 150K costs about $1.73 at the introductory price and $3.46 from 1 December. Output is where the money goes, so cap max_output_tokens on every background run and keep the volume work on a cheaper model.
Safety: what Google did, and what you still own
Google is holding Argon to four safeguards: refusing misuse (cyber and CBRN) while allowing legitimate dual-use research, resisting prompt injection (it leads Gray Swan’s indirect prompt injection benchmark), monitoring its chain of thought and actions for misalignment, and running it in sealed sandboxes during high-risk testing. None of that replaces your own controls. Give agents least-privilege keys, keep untrusted content apart from instructions, sandbox anything that executes code, and require a human to approve anything that cannot be undone. Our agent security guide and Ring Promoter QA gates show how we do that in practice.
The Workstation view
- Route, don’t replace. Argon is the lead for long, verifiable jobs. Fast models handle chat, classification and leaf tasks. See our model router guide; the same thinking applies across vendors.
- Measure before you trust. Run it on your own repo and your own documents with a baseline score, not a leaderboard.
- Ship through gates. Agent output goes int → test → acc → prod like any other change.
Want help piloting Argon on a real backlog? Talk to Workstation. We will pick one measurable workflow, build the verification harness, and run it through your normal release gates.