Observability Is Not Optional: Make It a Business Standard
For managers and owners: centralise telemetry, standardise platforms, and treat monitoring as a release requirement — not a team preference
 Balinder Walia2026年10月8日3 min read
For managers and business owners: observability is not a tool preference — it is how the company knows whether products, payments, and AI agents are healthy. Make it a centralised standard, not an optional side project. Technical companion: Big Prometheus, pros/cons, and MoSCoW of the tool landscape. Related: LLM bottlenecks & cost control.
Why this is a business decision, not an SRE hobby
When a checkout fails at 2am, leadership does not ask which open-source database won a benchmark. They ask: how long until we know, how long until we fix, and how do we stop this recurring? Those answers only exist if metrics, logs, traces, and alerts live in a shared system with clear ownership.
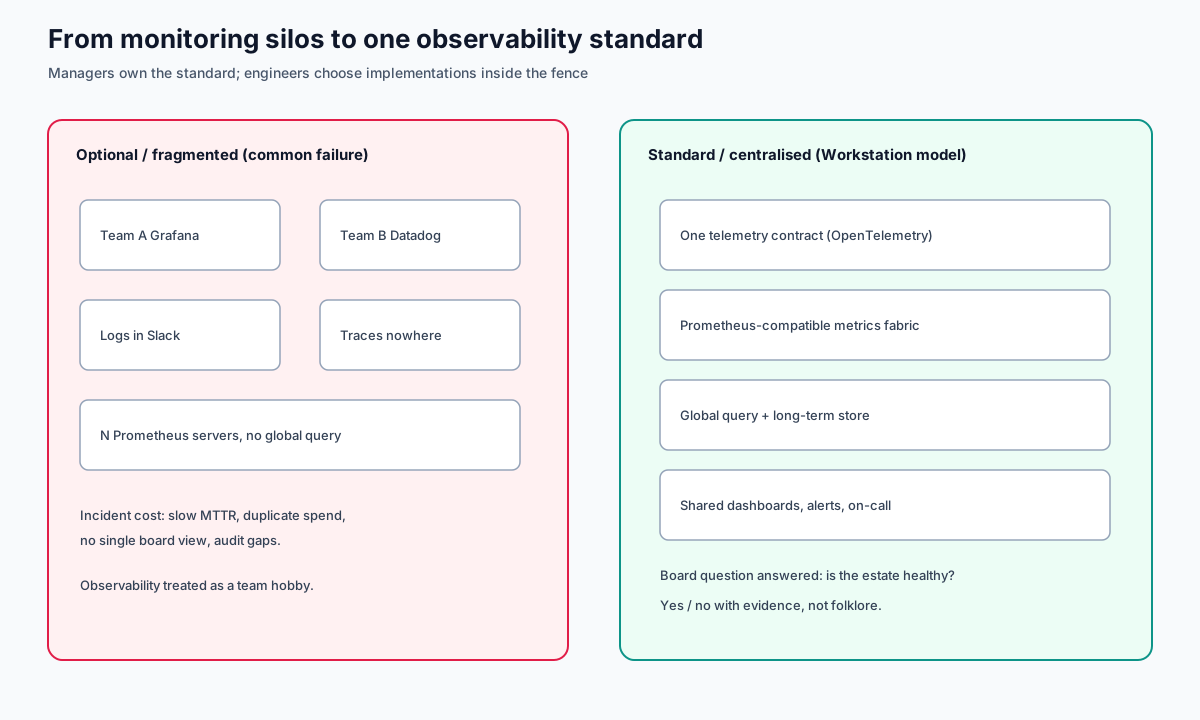
Optional observability creates predictable failure modes:
- Blind spots — a critical service “didn’t have time” to add metrics.
- Tool sprawl — three APMs, two log products, no single truth for SLOs.
- Cost surprises — high-cardinality labels and unsampled traces blow budgets.
- Audit gaps — regulators and enterprise customers ask for evidence; screenshots from Slack do not count.
What “centralised and standard” means in practice
Centralised does not mean one vendor forever. It means:
- One telemetry contract — every production service emits metrics, logs, and traces in approved formats (typically OpenTelemetry + Prometheus).
- One place to ask estate questions — “which clusters are on fire?” and “what was error rate seven weeks ago?” without hopping ten UIs.
- One on-call and alert taxonomy — severity, ownership, and escalation are shared language.
- One FinOps leash — retention, sampling, and cardinality budgets are policy, not heroics.
Inspired by the open-source “Big Prometheus” conversation (Thanos, Cortex/Mimir, M3, VictoriaMetrics), the engineering choice is how you scale that standard across many Kubernetes clusters — not whether you need a standard at all.
MoSCoW in one slide for leadership
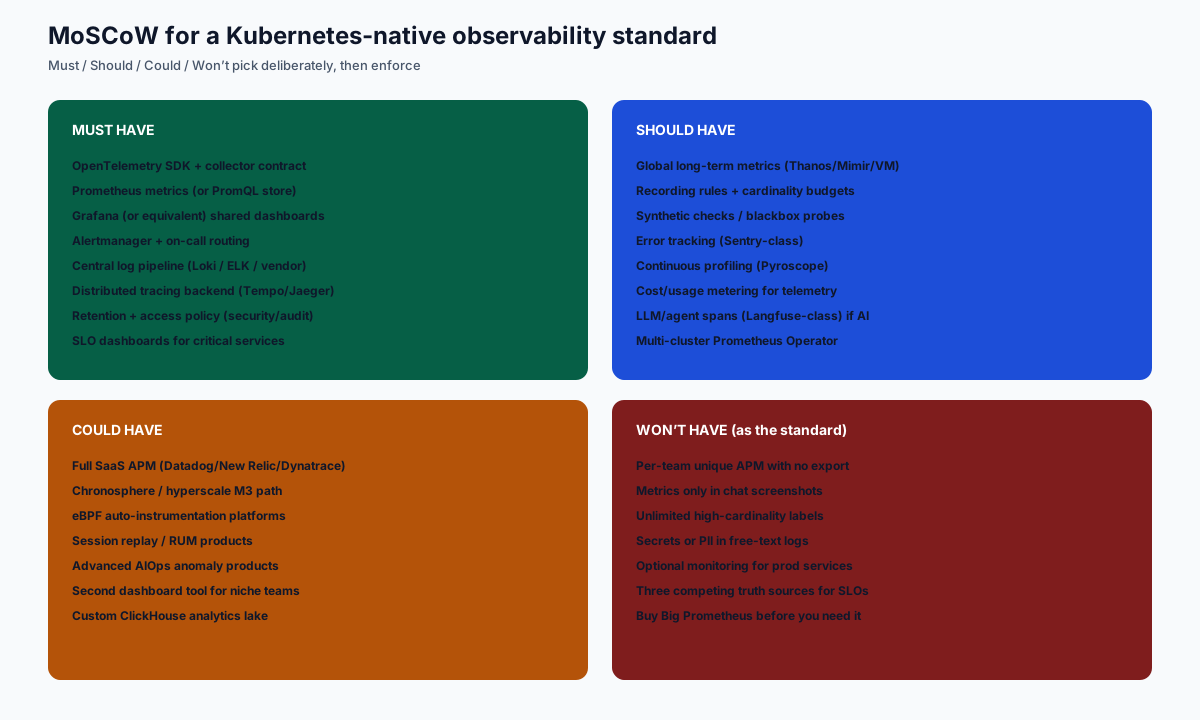
- Must — OpenTelemetry contract, PromQL metrics, shared dashboards, alerting/on-call, central logs, tracing, retention/access policy, SLOs for critical journeys.
- Should — global long-term metrics store, cardinality budgets, synthetics, error tracking, profiling, telemetry cost metering.
- Could — full SaaS APM, hyperscale commercial stacks, eBPF auto-instrumentation, RUM/session replay.
- Won’t (as the standard) — per-team unique APMs with no export, metrics-as-screenshots, unlimited cardinality, optional monitoring for production, three competing SLO sources.
What managers should fund and enforce
- Platform ownership — a small team owns the standard; product teams consume it.
- Definition of Done — no production release without golden signals and runbooks linked to alerts.
- Budget as policy — pay for retention and query performance deliberately; do not “save money” by going blind.
- Quarterly reviews — tool sprawl, MTTA/MTTR trends, and top cardinality offenders.
Workstation’s stance
Workstation runs GPU storefronts, AI agents, edge proxies, and promotion rings. Those surfaces only stay trustworthy if observability is mandatory across INT → TEST → ACC → PROD — the same discipline we apply to secrets and releases. For the engineering deep dive — Big Prometheus options, honest pros/cons, and a full MoSCoW of the tool landscape — read the technical article.
Want a single observability standard across your clusters and AI workloads? Talk to Workstation.