Uncovering LLM Bottlenecks: Observability, OTEL & Cost Control
Business brief: OpenTelemetry, Prometheus/Grafana, Langfuse — pros, cons, costs, and usage metrics that cut agent spend
 Balinder WaliaSeptember 4, 20264 min read
Workstation business brief: uncover LLM and agent bottlenecks with observability — OpenTelemetry, Prometheus/Grafana/Thanos, and LLM platforms such as Langfuse — so you can cut cost, tighten SLOs, and ship agents with evidence. Deep dive: long technical article (OTEL, FinOps, agent budgets). Related: Turbocharging LLMs · Enterprise AI Lab.
Why bottlenecks hide without telemetry
LLM agents chain prompts, tools, RAG retrieval, and retries. Latency and spend compound across hops. Without spans and metrics you cannot tell whether the bottleneck is the model, the vector store, a flaky tool, or an unbounded self-debug loop. Business stakeholders then over-buy GPUs or API quotas while product quality stays flat.
Workstation’s stance for AI estates: treat agent pipelines like any other production service — observability first, then optimise serving (see PagedAttention / vLLM), then promote with discipline (Ring Promoter).
The observability stack that pays for itself
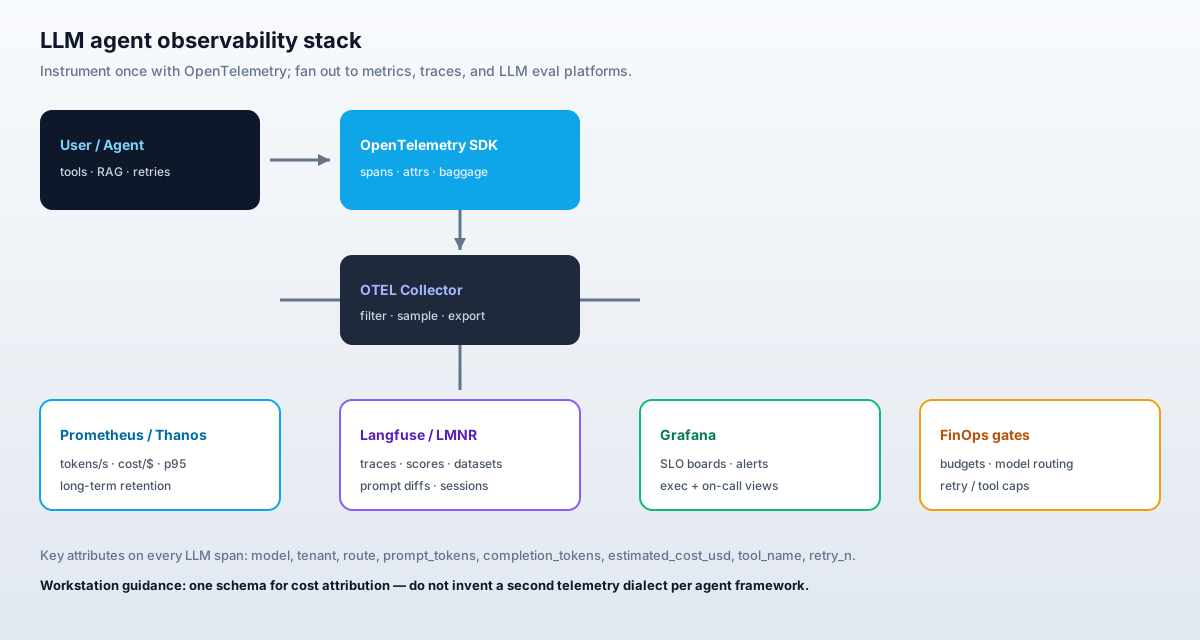
- OpenTelemetry (OTEL) — one instrumentation layer for traces, metrics, and (where useful) logs. Export to a collector; fan out to backends.
- Prometheus + Grafana (+ Thanos) — golden signals: request rate, error rate, latency, token throughput, estimated $/request, GPU utilisation. Thanos (or equivalent) keeps long-term metrics for FinOps reviews.
- LLM observability platforms (e.g. Langfuse, LMNR) — session/trace UI, prompt versions, human & automated scores, datasets for regression.
Pros and cons of this approach
| Dimension | Pros | Cons / trade-offs |
|---|---|---|
| Cost control | Attribute spend to tenant, feature, model, and agent step; kill wasteful retries. | Engineering time to instrument; storage cost for traces if retention is naive. |
| Quality | Scores + datasets catch prompt regressions before customers do. | Automated scoring can be noisy; humans still needed for critical paths. |
| Ops | Same OTEL/Prometheus skill set as your other microservices. | LLM-specific UIs (Langfuse etc.) add another product to run or buy. |
| Compliance | Audit who called which model with which prompt version. | Prompt/PII retention policies must be designed up front. |
| Speed to value | First dashboards in days if you already run Grafana. | Full cost attribution across multi-agent graphs takes longer. |
Costs: what you spend vs what you save
Instrumentation cost (typical mid-size agent platform):
- 1–2 engineer-weeks to adopt OTEL span conventions + exporter wiring.
- Collector + metrics retention: often <5–10% of monthly LLM API/GPU spend once sampling is tuned.
- Optional SaaS LLM observability: priced per event/trace — budget it as a % of model spend, not as an afterthought.
Savings levers (usage metrics that move the needle):
- Tokens per successful task — not tokens per raw call. Cap tool loops and self-debug rounds.
- Cost per successful task — route cheap models for classify/route; reserve frontier models for hard steps.
- Cache hit rate — prompt/prefix caching where safe; measure correctness, not only latency.
- Retry rate & dead-letter rate — flaky tools masquerade as “model quality” issues.
- p95 TTFT and end-to-end latency — protect UX while you cut spend.
Scoring: manual vs automatic
| Method | When to use | Business note |
|---|---|---|
| Manual scoring | Gold sets, regulated answers, brand-sensitive copy. | Expensive but grounds automated judges. |
| Automatic scoring | High-volume regression, LLM-as-judge, rubric checks. | Cheap at scale; calibrate against humans monthly. |
Migration playbook (start small)
- Instrument one production agent path end-to-end with OTEL + token/cost attributes.
- Ship a Grafana board for rate / errors / latency / $/success.
- Add Langfuse (or equivalent) for prompt versions and scores on that path.
- Enforce hard caps: max tokens, max tool calls, max retries per session.
- Expand to the next agent only after the first path shows a measured cost or latency win.
Watch: why observability matters for AI systems
Context talk on observability culture — not a Workstation product demo. Pair with OpenTelemetry docs and the Workstation technical article.
Read next
- Long article — OTEL span schema, collectors, cost formulas, agent caps, Langfuse/LMNR notes.
- Turbocharging LLMs — serving-side bottlenecks after you can see them.
- Local agents · Enterprise AI Lab · Contact Workstation
Published by Workstation. References: langfuse/langfuse · lmnr-ai/lmnr · OpenTelemetry.