Insights & Guides
Technical Notes
Deep dives on AI infrastructure, MLOps, GPU clusters, and building with agents.
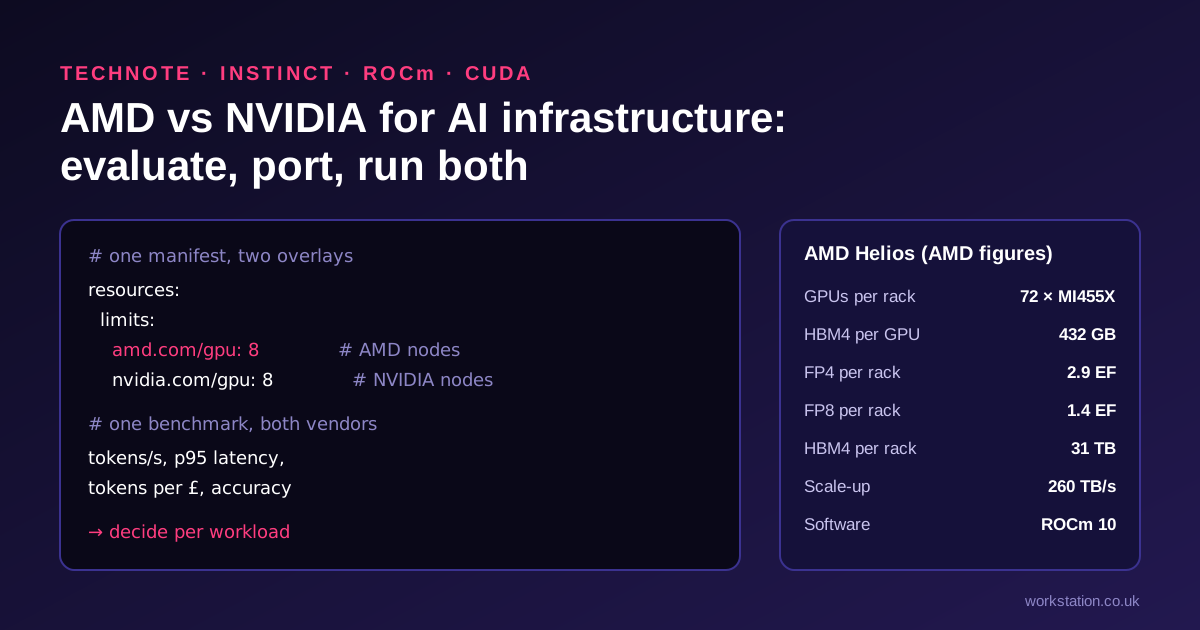
AMD Instinct vs NVIDIA for AI Infrastructure: Evaluate, Port and Run Both (2026)
From Lisa Su's 2024 interview to Helios: the 2026 platforms layer by layer, Instinct product lines, memory arithmetic, the CUDA-to-ROCm software map,…
11 min readRead more
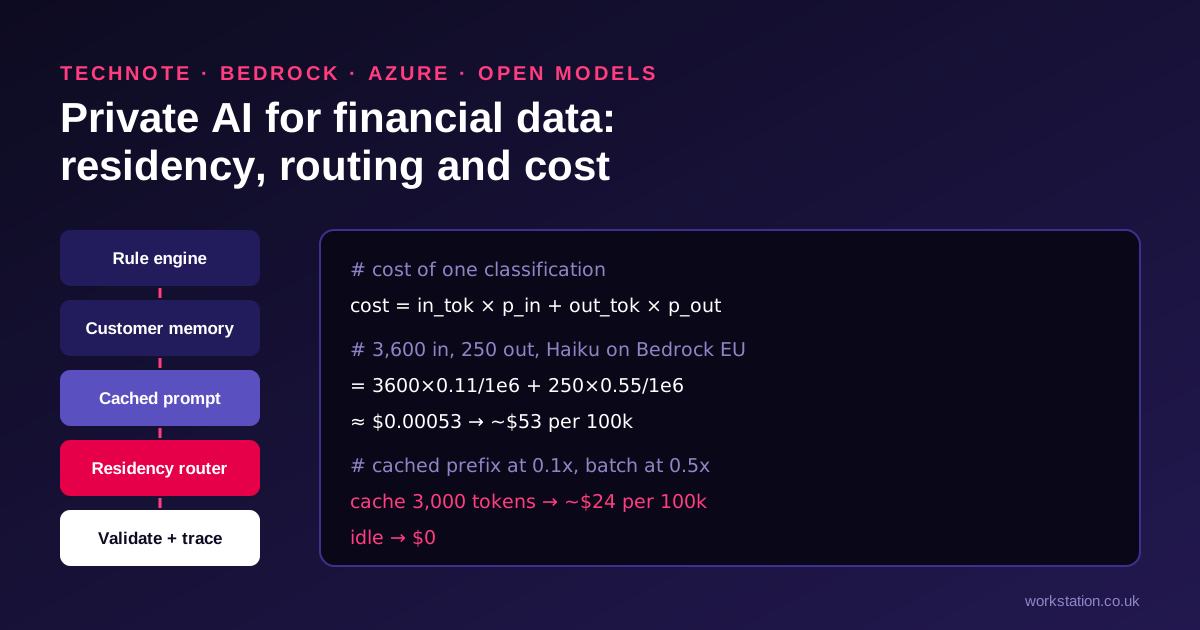
Private AI for Financial Data: Residency, Routing and Cost on AWS Bedrock, Microsoft Azure and Your Own GPUs
Billing models and idle cost, per-call cost at three volumes, Bedrock in-region vs EU profiles, Converse API with prompt caching and IAM region enfor…
16 min readRead more
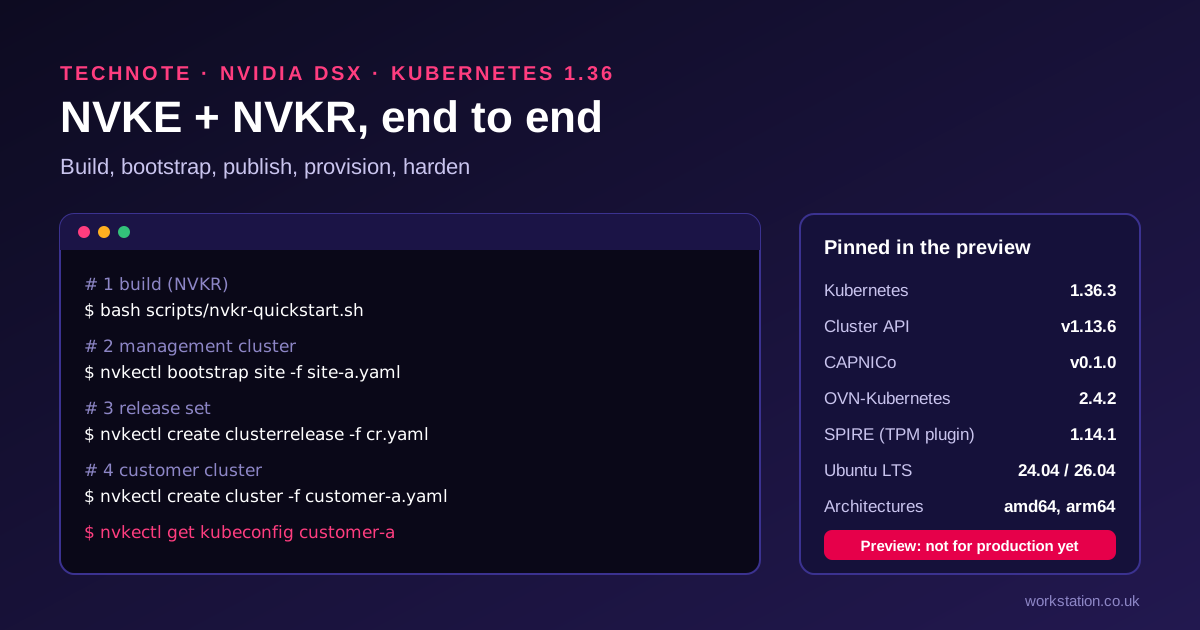
NVKE and NVKR Technote: Building a Managed GPU Kubernetes Service from Bare Metal, with Reproducible, Verifiable Builds
Architecture, components and pinned versions, the NVKR Definition-Run-Release-Verify lifecycle, the full nvkectl workflow from racked servers to a cu…
21 min readRead more
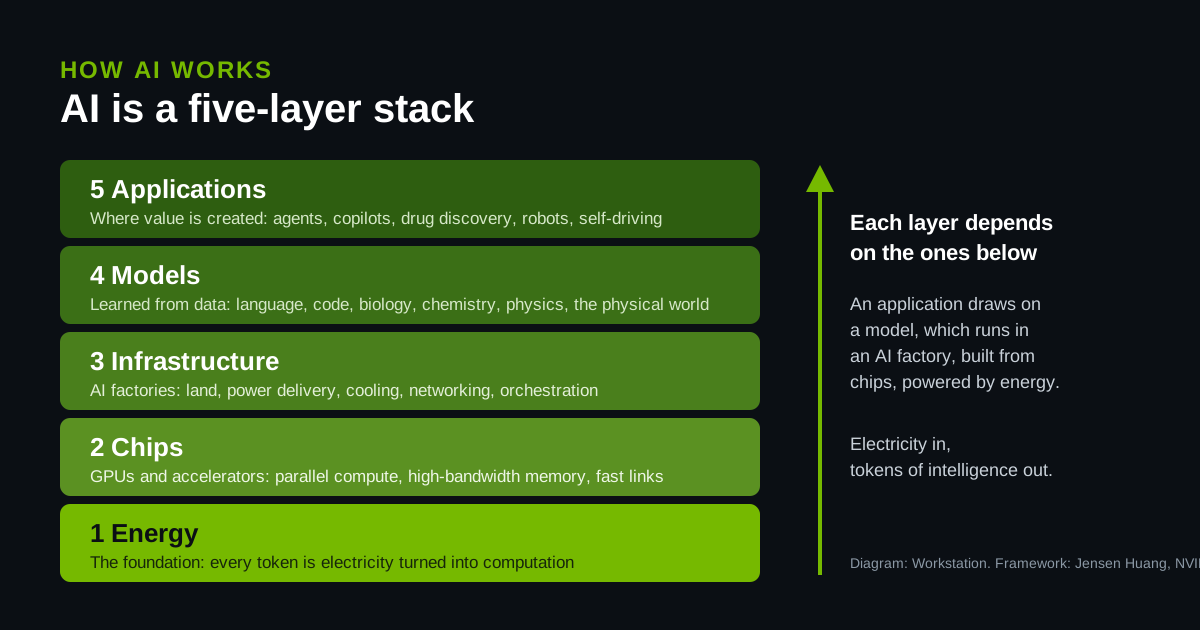
AI Is a Five-Layer Cake: What AI Is, How It Works and Why Every Layer Matters
Jensen Huang's framework explained: energy, chips, infrastructure, models and applications, how each layer depends on the ones below, and what it mea…
8 min readRead more
Jensen Huang on Building the Dynamo of the Intelligence Age: AI Factories, Tokens and Jobs
Notes on NVIDIA founder Jensen Huang's Sequoia Capital interview: why computing is moving from retrieval to generation, why AI factories are this era…
6 min readRead more
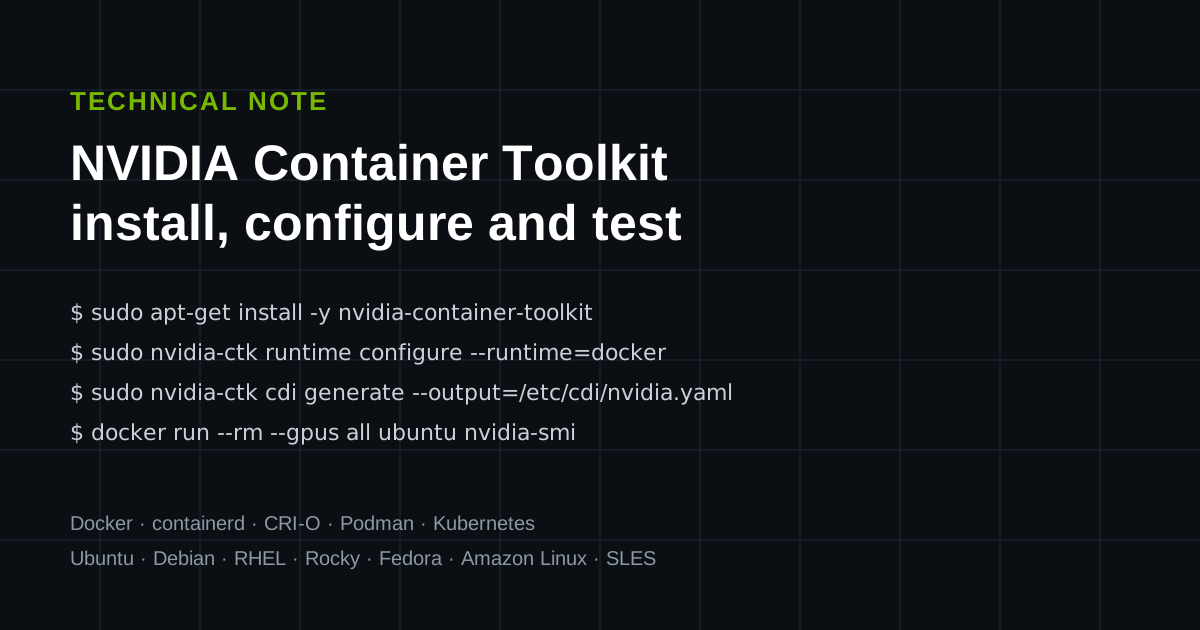
Installing the NVIDIA Container Toolkit: Docker, containerd, CRI-O, Podman and Kubernetes
Install the toolkit with apt, dnf or zypper, configure every container engine, use CDI, test GPU access, and fix the errors you will meet, with advic…
14 min readRead more
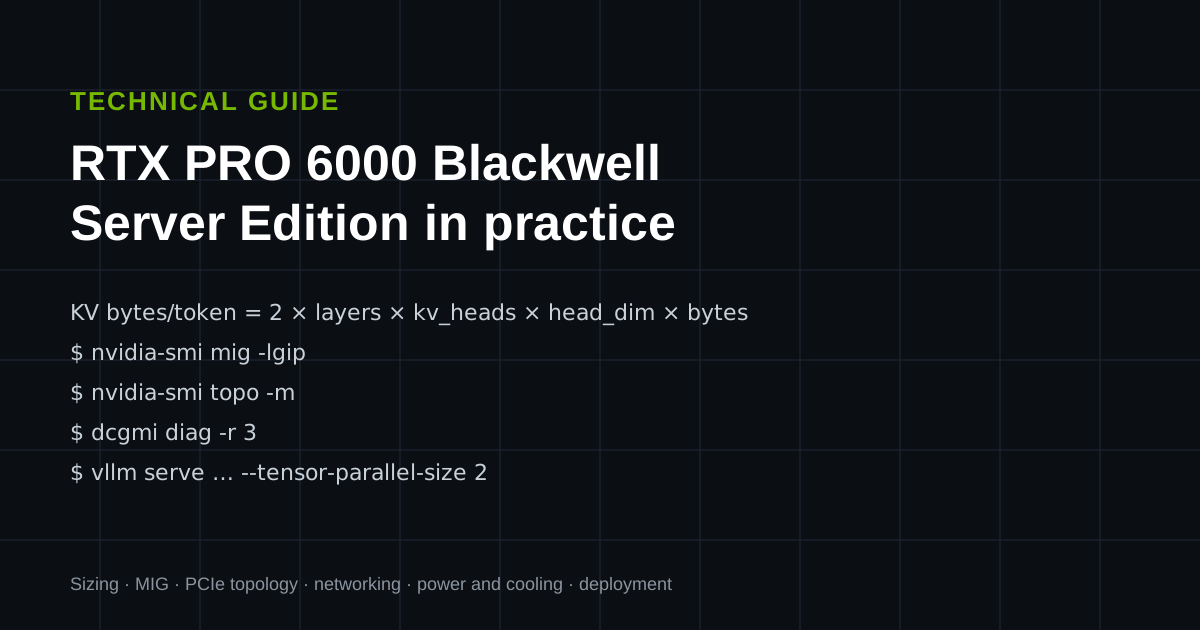
NVIDIA RTX PRO 6000 Blackwell Server Edition in Practice: Memory Sizing, MIG, PCIe Topology, Networking, Power, Cooling and Deployment
Specifications, weights and KV-cache sizing with worked examples, MIG, PCIe topology without NVLink, networking between servers, UK power and cooling…
15 min readRead more