The Workstation Blog
LLM
Posts tagged LLM.
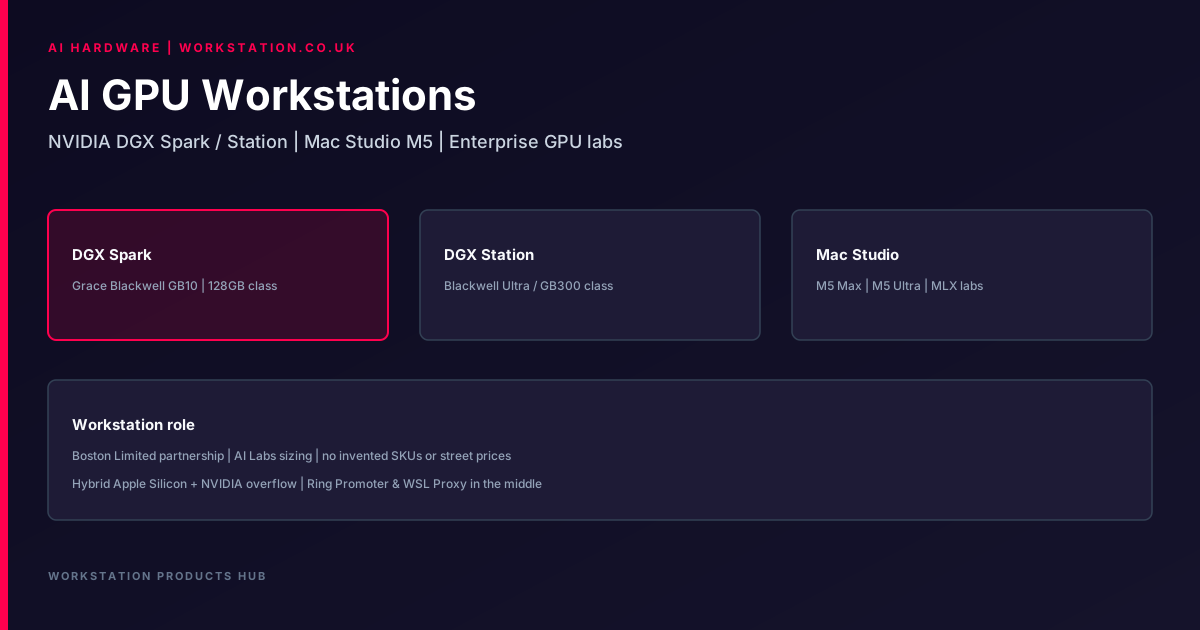
AI GPU Workstations: NVIDIA DGX Spark/Station & Mac Studio M5
How Workstation maps NVIDIA DGX Spark, DGX Station, and Mac Studio M5 into AI Labs and SME packages — factual positioning, no invented prices.
 Balinder WaliaRead
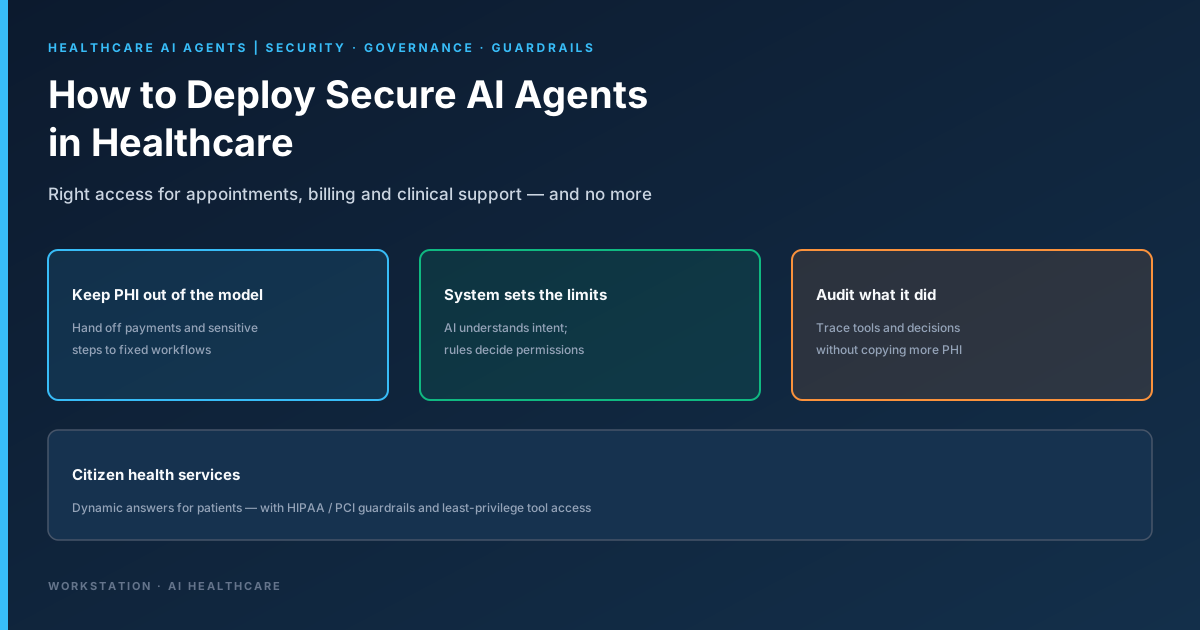
How to Deploy Secure AI Agents in Healthcare
AI agents can book appointments, take payments and support clinical work. Here is how healthcare teams can give them the right access, and no more.
Balinder WaliaRead 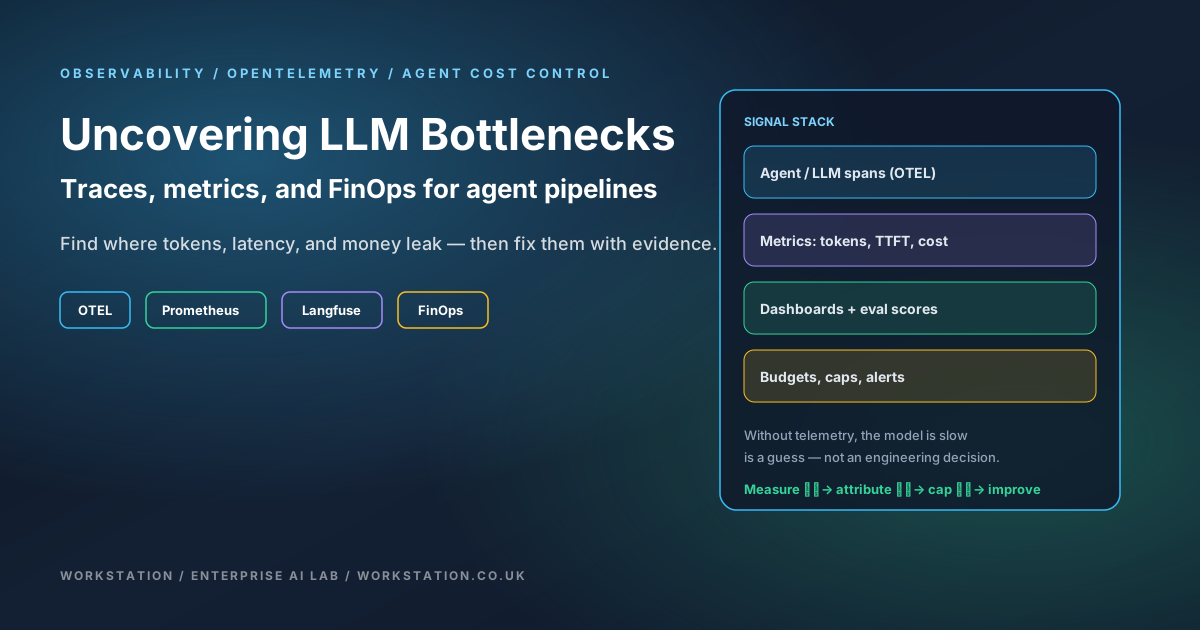
Uncovering LLM Bottlenecks: Observability, OTEL & Cost Control
Workstation on uncovering LLM agent bottlenecks with observability: OpenTelemetry, Prometheus/Grafana/Thanos, Langfuse — with clear pros/cons, cost levers, and usage metrics that protect margins.
Balinder WaliaRead 
Turbocharging LLMs
Workstation on turbocharging LLMs: PagedAttention paging for KV cache, vLLM serving, Self-Debugging for agents, PowerInfer token rates, and EG-MLA memory cuts — with production trade-offs.
Balinder WaliaRead 
KubePilot: CoPilot, Pilot & AutoPilot for Faster Kubernetes Incidents
KubePilot helps SRE, DevOps, and platform teams move from noisy cluster signals to a safe fix — CoPilot, Pilot, and AutoPilot. Open source at kubepilot.org.
Balinder WaliaRead 
Muse Glimmer on Ollama: Always-On Local Agents on One GPU
Meta Muse Glimmer brings always-on local agents to a single GPU via Ollama: 30B, Apache 2.0, 128K context, vision and tools — Workstation business guide.
Balinder WaliaRead 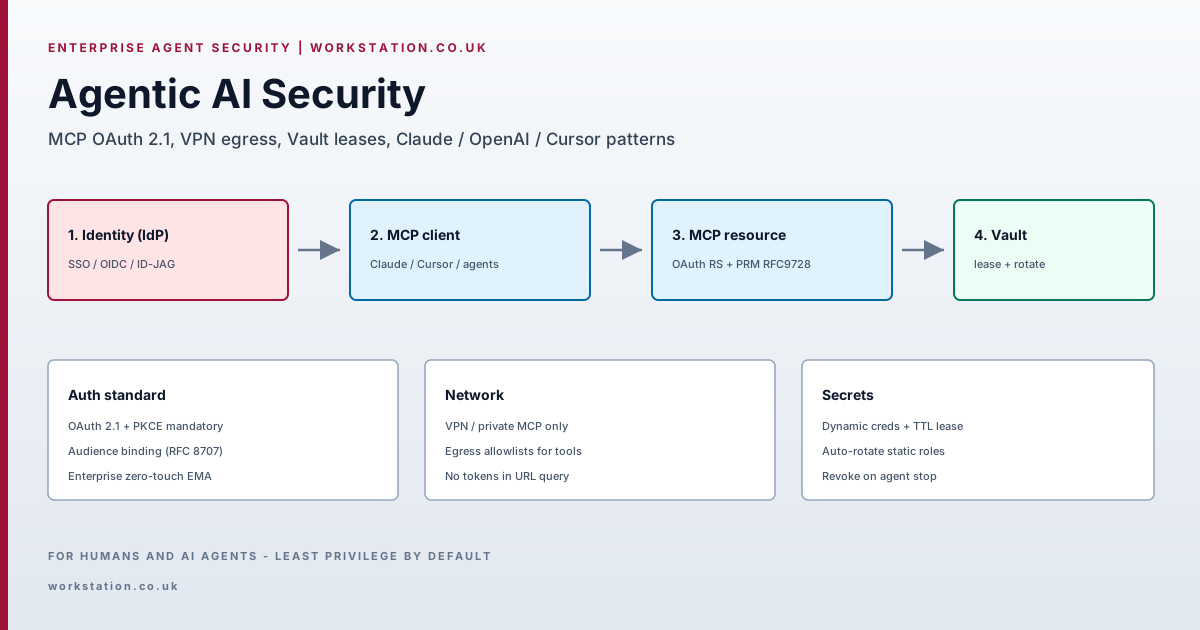
Agentic AI Security: MCP OAuth, VPN & HashiCorp Vault Leases
Secure enterprise AI agents with MCP OAuth 2.1, VPN-isolated tools, and HashiCorp Vault leases that auto-rotate and expire — plus Claude, OpenAI, and Cursor recommendations.
Balinder WaliaRead 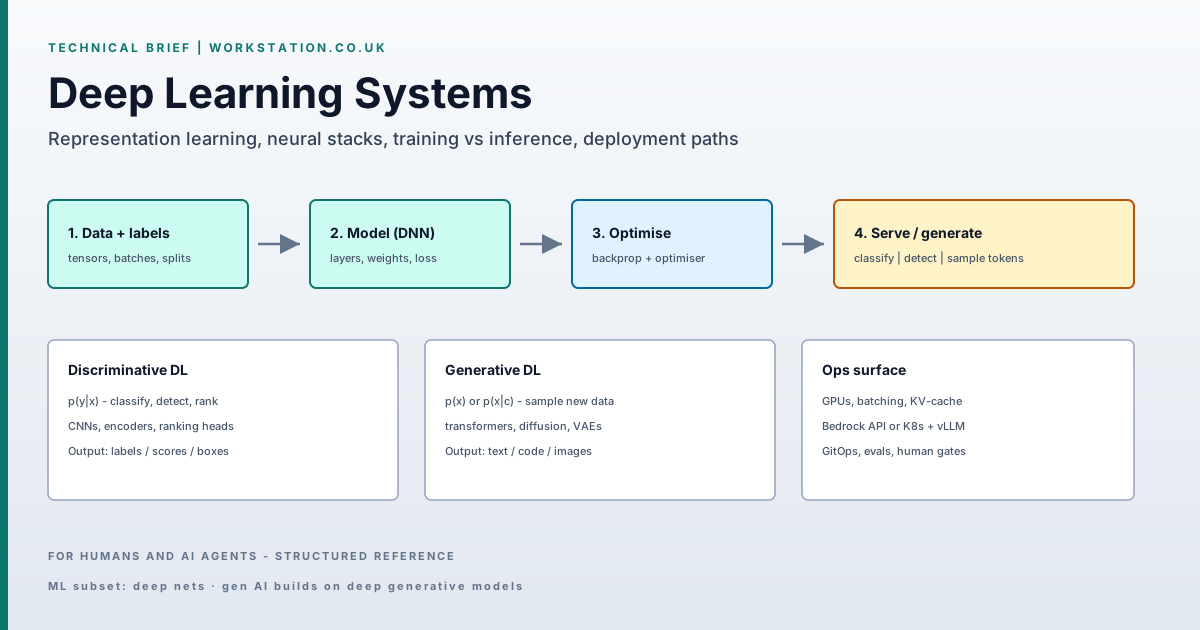
What is Deep Learning? Workstation Guide for Builders & Business
Workstation rewrite of AWS What is Deep Learning: neural networks, generative AI, vision/speech/NLP/recommendations, and how teams ship DL in the cloud or on Kubernetes.
Balinder WaliaRead