NVIDIA Minerva for AI Factories: Turning Alert Storms into Recovered GPU Hours
What Minerva does, which consumption model fits whom, three worked examples, and how Workstation supplies, integrates and supports it
 Balinder Walia2026年11月9日11 min read
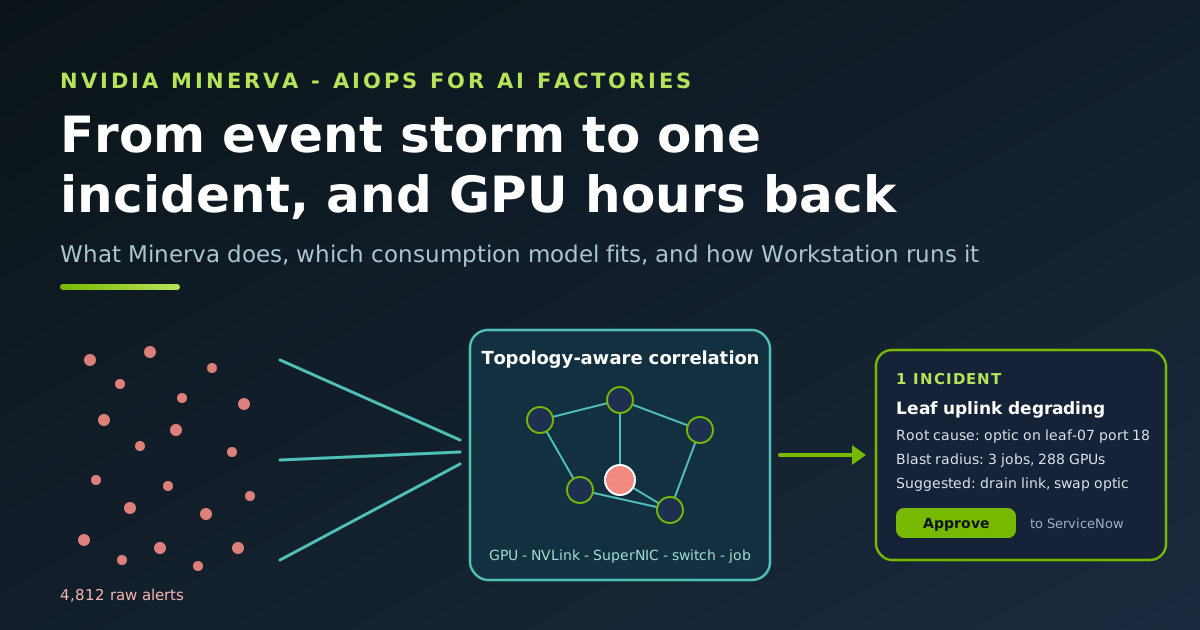
An AI factory earns its keep in GPU hours and tokens, and it loses them quietly: a straggling node, a degrading optic, a storm of alerts nobody can read in time. This post is for CTOs, AI-factory and neocloud operators and heads of research computing. It explains in plain terms what NVIDIA Minerva is, what it is worth to the business, which of its three consumption models fits which organisation, how it relates to NVIDIA UFM, and how Workstation supplies, sets up, integrates and supports it. Engineers who want the architecture, the integration configuration and the rollout runbook should read the technical article.
Interactive version: open seventeen example dashboards for a Minerva deployment, from AI factory yield to collector health, with the signals and alert guidance behind each one.

What NVIDIA Minerva is, in plain terms
NVIDIA announced Minerva in October 2026 and describes it on its official NVIDIA Minerva page as the main observability product for its AI factories, including systems built on the Vera Rubin and Blackwell platforms. Stripped of the jargon, it does five things:
- Collects everything once. GPU health, the NVLink switches that join GPUs inside a rack, Spectrum-X Ethernet switches and SuperNICs that join racks together, DPUs, NCCL (the library GPUs use to exchange results), the job schedulers such as Slurm and NVIDIA Run:ai, storage and the AI workloads themselves. It takes this in through open standards: OpenTelemetry, gNMI streaming from switches, syslog, DCGM for GPUs, Slurm data and plain JSON.
- Keeps a live map. A knowledge graph records which GPU sits in which node, which port connects to which switch, and which job is running where, and it updates as jobs come and go.
- Learns normal and spots the odd. Machine learning builds a baseline for each signal and flags the drift that usually comes before a failure.
- Explains, not just alerts. When something goes wrong, it walks the map to find the shared cause behind the symptoms, works out which jobs and GPUs are affected, and sends a single incident to Slack, Microsoft Teams, PagerDuty or ServiceNow.
- Talks back. An assistant called Sherlock lets operators ask questions in plain English against live telemetry, and an MCP (Model Context Protocol) server lets your own AI agents query Minerva. Where you allow it, recommended fixes can be carried out automatically, for example through Ansible.
It can run in your data centre or as a service hosted by NVIDIA, and NVIDIA says it scales to hundreds of thousands of GPUs. The Minerva Collector is also part of NVIDIA DSX OS, which lets the same view stretch from the GPU to the building's power and cooling.
Why it matters to the business
An AI factory is a very expensive machine whose output is tokens and trained models. Anything that stops it, slows it or makes it hard to fix shows up directly in cost per token. NVIDIA frames Minerva's value in the same terms operators already report on, and so do we:
- Recovered GPU hours. Faults that silently slow jobs, such as a single straggling node holding up thousands of GPUs at every synchronisation step, are found in minutes rather than days.
- Higher goodput. Goodput is the share of GPU time that produces useful work, after restarts, re-runs and waiting are taken out. It is the number that matters, not raw utilisation.
- Fewer interruptions (higher MTBI). Mean time between interrupts goes up when failing parts are spotted early and swapped in a planned window instead of mid-run.
- Faster repair (lower MTTR). Mean time to repair falls when the first message already names the probable cause and the blast radius.
- Calmer on-call. One incident instead of thousands of alerts means people respond to the right thing, and stay in the job.
- More tokens. For inference, every hour of degraded throughput is lost output and, for a provider, lost revenue.
- Data sovereignty. On-premises deployment keeps telemetry, topology and job metadata inside your own estate, which matters for UK public sector, research and regulated customers.
Three consumption models, and who each one suits
NVIDIA offers Minerva in three ways, from do-it-yourself to fully turnkey. We help customers choose by asking what they already run and how much of the analysis they want to own.
| Model | What you get | Suits | Think about |
|---|---|---|---|
| DIY Observability | Minerva as the collector for AI factory telemetry, feeding your own observability tools such as Grafana. | Teams with a mature Prometheus and Grafana practice who want NVIDIA-aligned data collection without changing their tools. | You build and maintain the dashboards, alerts and correlation yourself. |
| AIOps with DIY Observability | The collector plus Minerva's machine learning, anomaly detection and correlation, with the insights fed back into your existing tools and agents. | Enterprises with an established Grafana, ServiceNow or PagerDuty stack who want fewer, better alerts without a new console. | Integration and alert routing need careful design, so incidents land in the right queue once. |
| Turnkey | The complete platform: collection, insights, the Sherlock assistant and Minerva's own dashboards and user interface. | AI factories and neoclouds that want a single operations view aligned with NVIDIA's reference architectures from day one. | Decide early how it coexists with any monitoring you already run for non-GPU systems. |
Licensing, editions and support terms come from NVIDIA and can change, so we confirm them for every quote. The choice is also not permanent: many customers start with the collector and add AIOps once they trust the data.
Three examples
The numbers below are illustrative, worked through to show the shape of the business case. Your GPU-hour cost, job mix and failure rates will differ.
1. A neocloud with about a thousand Vera Rubin GPUs
Fourteen Vera Rubin NVL72 racks, 1,008 GPUs, on a Spectrum-X Ethernet fabric, rented to customers for large training runs and inference. At an illustrative fully loaded cost of £6 per GPU-hour, the estate represents about 8.8 million GPU-hours a year, so every 1% of lost goodput costs around £530,000.
- Our usual recommendation: Turnkey Minerva on premises, with the collector deployed as part of DSX OS so facility power and cooling sit on the same timeline as the GPUs, and incidents routed to the provider's ServiceNow.
- Where the money is: suppose a tenant's training job spans eight racks (576 GPUs) and each interruption loses about 50 minutes of work and restart time, roughly 480 GPU-hours. Moving from one interruption every two days to one every three days avoids about 60 interruptions a year, around 29,000 GPU-hours or £175,000 for that one job class.
- Example: a node with a slowly degrading NVLink connection becomes a straggler. Without correlation the job simply runs 15% slower and the customer complains days later. With it, the straggler is named within minutes, the job is moved off the node at its next checkpoint, and the tray is serviced in a planned window.
2. A university with a 256-GPU Blackwell cluster
Thirty-two HGX B300 servers, 256 GPUs, shared by research groups through Slurm, run by a small central team who already use Grafana for everything else. At £2.50 per GPU-hour, 1% of the cluster's year is about 22,400 GPU-hours, or £56,000.
- Our usual recommendation: start with DIY Observability, sending Minerva-collected data into the team's existing Grafana, with GPU and job data tagged by Slurm job so each department sees its own usage. Move to AIOps with DIY Observability once the team wants automated root-cause analysis of failed jobs.
- Business outcome: evidence-based answers to the two questions every research computing service gets: "why did my job fail?" and "who used the GPUs?". That supports chargeback, funding bids and fair scheduling.
- A note on the fabric: if the cluster's GPU network is InfiniBand rather than Spectrum-X Ethernet, NVIDIA UFM remains the tool that runs and watches that fabric; see our UFM post. We confirm with NVIDIA how Minerva and UFM data are combined for the release you buy.
3. An enterprise with Grafana, ServiceNow and PagerDuty already in place
A financial services firm runs 128 Blackwell GPUs (sixteen HGX B300 servers) for internal inference, about 2 billion tokens a day. Its operations team already lives in Grafana, ServiceNow and PagerDuty and does not want another console.
- Our usual recommendation: AIOps with DIY Observability, on premises for data sovereignty. Minerva's correlated incidents create ServiceNow tickets and PagerDuty pages; its insights appear in the existing Grafana; Sherlock and the MCP server are enabled read-only for the platform team.
- Business outcome (illustrative): around 3,000 raw alerts a week become a few dozen incidents, and pages to the on-call engineer drop from over a hundred a week to around fifteen. Typical repair time falls from about three hours to under an hour because the ticket already names the cause.
- Token impact: a four-hour slowdown that cuts throughput by 30% costs about 100 million tokens of output. Catching it in 30 minutes instead keeps most of them.
Minerva and UFM: which does what?
Our earlier post on NVIDIA UFM covered Unified Fabric Manager, NVIDIA's software for running and monitoring InfiniBand fabrics: subnet management, partitions, fabric telemetry and failure prediction. Minerva has a different scope:
- UFM is a fabric manager. It configures and operates an InfiniBand network and reports on its health.
- Minerva is an AIOps platform for the whole AI factory. On NVIDIA's description it spans compute, NVLink scale-up, Spectrum-X Ethernet scale-out and scale-across, schedulers, storage and workloads, and its job is correlation and diagnosis across all of them, not running the network.
So an InfiniBand cluster still needs a subnet manager such as UFM, and a Spectrum-X AI factory gets its network observability from Minerva. Where a site has both, we design one labelling scheme and one incident flow so the two do not page people twice.
What Workstation does
We are a UK reseller and integrator of NVIDIA AI infrastructure. For Minerva that means:
- Supply. The Minerva licence at the right model, together with the systems it watches: Vera Rubin NVL72 racks, DGX and HGX systems, Spectrum-X Ethernet, SuperNICs and BlueField DPUs.
- Set up and integrate. We deploy the collectors and, where needed, an OpenTelemetry tier for your existing sources; connect Minerva to Slack or Teams, PagerDuty and ServiceNow; feed Grafana; configure Slurm or Run:ai metadata; and run a baselining period before anything pages anyone.
- Make automation safe. Sherlock and MCP access start read-only. Remediation runs through approved Ansible playbooks with change records, and we prove it with fault drills before handover.
- Support and run. Our engineers support Minerva and the surrounding software services day to day, tune noise reduction, keep the collector tier healthy and highly available, and report monthly on GPU hours, goodput, MTBI and MTTR. We work alongside your team and NVIDIA support.
Questions to ask before you buy
- What does an hour of your AI factory cost, and how much goodput do you think you are losing today?
- Which tools does your operations team already live in, and should Minerva feed them or replace them?
- Must telemetry and job metadata stay on premises, and who may see it?
- How much automation will your change process allow, and who approves it?
- Is your GPU fabric Spectrum-X Ethernet, InfiniBand, or both?
NVIDIA partner: engineering, software and people
Workstation is an NVIDIA partner. Beyond supplying the hardware, we provide the engineering, software and staff to plan, build and run AI data centres: site and power surveys, rack and fabric design, Spectrum-X, NVLink and InfiniBand installation, Minerva, UFM, DCGM and OpenTelemetry set-up, Kubernetes, Run:ai and Slurm onboarding, and engineers who stay with you through handover and managed support. For NVIDIA's own description of the product, see the official NVIDIA Minerva page and the Minerva datasheet (both open in a new tab).
Next steps
Open the interactive dashboard gallery to see the seventeen views we set up around a Minerva deployment. Then look at NVIDIA Minerva in our shop, or ask our AI Sales Engineer to size the deployment, the consumption model and the systems around it. We are happy to start with an observability review of an AI cluster you already run.
Figures in this post are illustrative examples, not measurements from a specific customer.
Acknowledgement of rights: NVIDIA, the NVIDIA logo, Minerva, Sherlock (as the name of NVIDIA's assistant), DSX, DSX OS, DGX, HGX, Vera Rubin, Blackwell, Spectrum, Spectrum-X, NVLink, ConnectX, SuperNIC, BlueField, DCGM, NCCL, Run:ai and Unified Fabric Manager (UFM) are trademarks and/or registered trademarks of NVIDIA Corporation in the United States and other countries. NVIDIA products and technologies may be covered by patents and other intellectual property rights owned by NVIDIA Corporation, and all such rights are acknowledged and reserved to their owners. Product information is summarised in our own words from NVIDIA's public material; NVIDIA's website and documentation are the authoritative source. Other company and product names, including Grafana, Prometheus, Slack, Microsoft Teams, PagerDuty, ServiceNow, Ansible, OpenTelemetry, Slurm and Kubernetes, may be trademarks of their respective owners. Workstation's own dashboards, configurations and text are © Workstation.