Workstation 部落格
MLOps
標記為 MLOps 的文章。
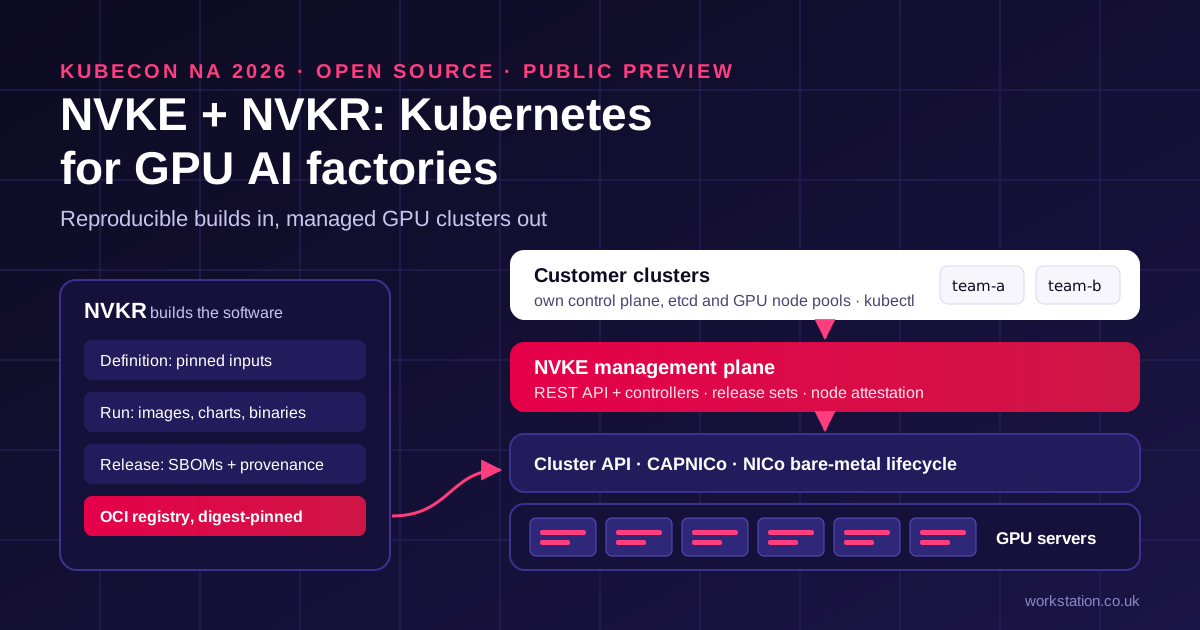
NVIDIA NVKE and NVKR: Why GPU Kubernetes Is Becoming the AI Factory's Operating System
NVIDIA has open-sourced NVIDIA Kubernetes Engine (NVKE) and NVIDIA Kubernetes Recipes (NVKR) to run managed Kubernetes on GPU infrastructure. What they do in plain terms, what public preview really means, why AI engineering is creating new demand for cloud and DevOps skills, and who should evaluate them now.
 Balinder Walia閱讀
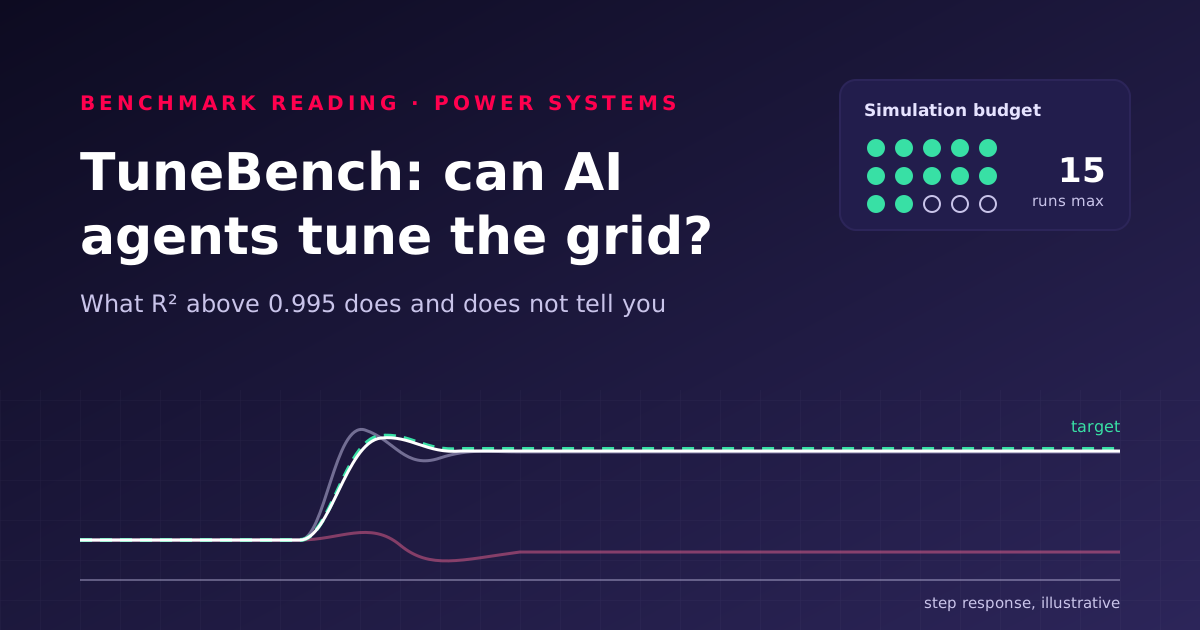
TuneBench: How Well Can AI Agents Calibrate Power System Models?
TuneBench tests LLM agents on calibrating generator and battery models within 15 simulations. Only Opus 5.5 and GPT-6 hit median R² above 0.995 in every test. What that figure means, its limits, and how to build the same kind of benchmark.
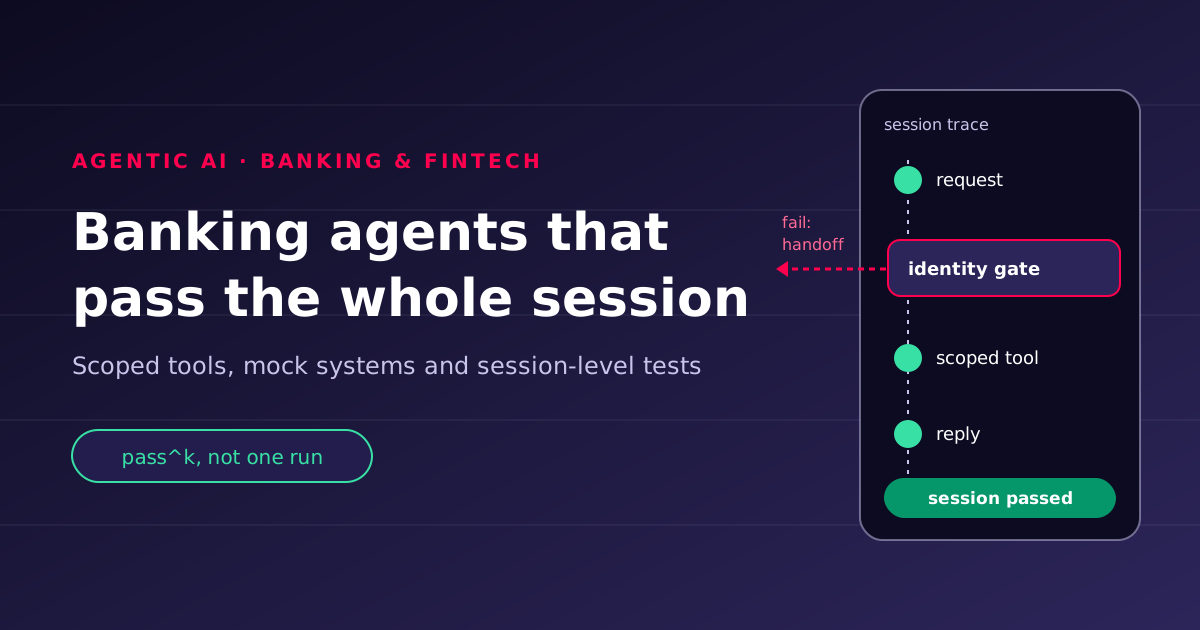
Agentic AI in banking: efficiency you can defend to a risk committee
Banking AI agents rarely fail on one bad reply; they fail across a session. How to scope tools, test whole conversations against mock systems and measure reliability with pass^k, so the time saved survives audit and production.
Wikipedia banned AI-written articles: what teams that reuse it should change
English Wikipedia now prohibits LLM-written article text, yet volunteers still flag a steady share of new drafts as AI-generated. If your search, chatbot or knowledge base reuses Wikipedia, here is how to pin revisions, watch edits, review changes and attribute correctly.
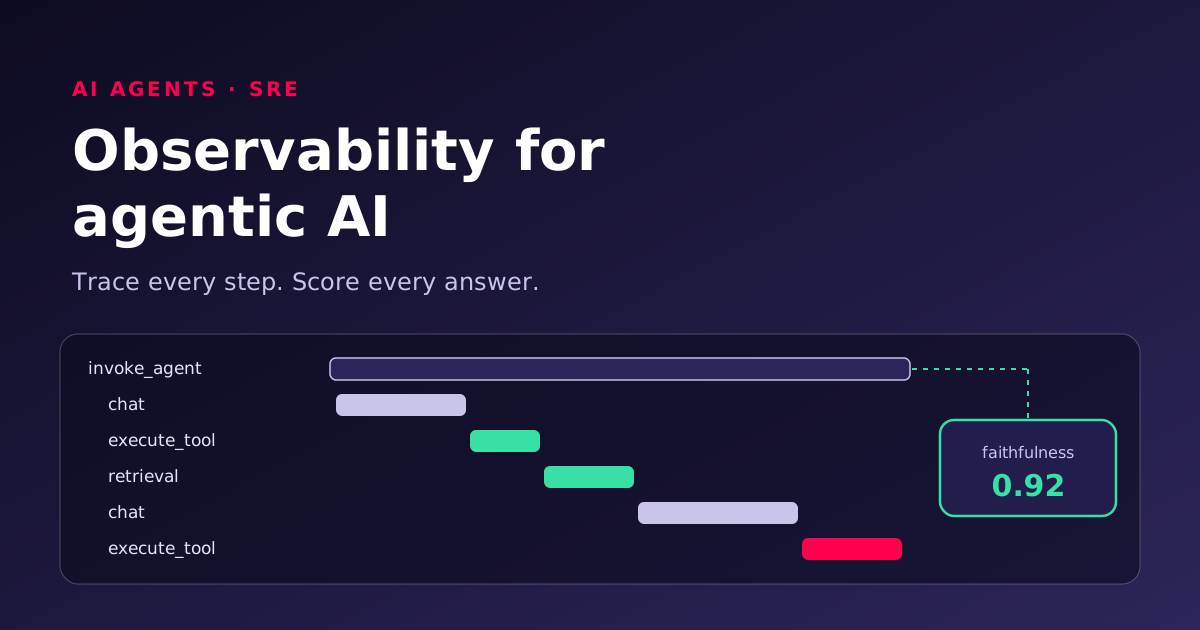
Observability for Agentic AI: Tracing, Evaluating and Auditing Agents
AI agents fail quietly: a confident answer from the wrong document, a tool called with the wrong argument. Learn how to trace every model, retrieval and tool step with OpenTelemetry, attach quality scores, and keep the records auditors ask for.
The energy cost of LLM code optimisation, and when it pays back
A 2026 study found LLM-optimised code used more energy per run than the human reference in 42 of 44 configurations. Learn the break-even rule, how to measure joules per run on Linux, and a workflow for keeping only the rewrites that pay back.
Pixel-Space Diffusion Is Back: What Changed and How to Evaluate It
Diffusion directly on pixels now competes with latent diffusion, without a separately trained autoencoder. What HDiT, SiD2, JiT and 2026 research changed, where pixel models still lose detail, and a practical way to test the trade-off on your own images.
Cutting LLM Inference Costs: Lessons from Cloudflare's 68% Cut
Cloudflare cut its AI code reviewer's average cost per review by 68%. Here is what that number does and does not mean, and a measured playbook for your own workload: prompt cache breakpoints, fewer agent calls, right-sized models and batch.